此内容尚未翻译。显示英文原文。
Jev, Clef, Haiku, or nothing?
What a decision model is, who makes them, and what happened when I put them in front of six AI models for 3,264 runs
2026年10月6日 · 6 min · 更新于 2026年10月8日 · 原始 .md
Written on 6 October 2026, three weeks after Jev launched and five days after Clef. These models, their prices and their APIs are changing fast, so treat every number here as true on that date. Message me if you are working on this too.
Updated 8 October 2026. OpenAI opened its own decision model, Luna Decisions, on 6 October. I tested it next to Jev on the same requests: Jev against Luna.
This is the short version. The full guide has every model and setup side by side, interactive.
You’ve probably heard about Jev by now. I like to run my own evals before I say much about a model, and by the time I started, more had shown up: Cloudflare’s Clef and Clef-flash, with open weights, Liquid’s d1 and Laya. So I tested them on the same job, side by side, and wrote down what each one is and who makes it.
What a decision model is
A decision model answers questions you give it about a situation, and only those questions. You send the situation as text or JSON, plus a short list of typed questions: pick one of these options, answer yes or no, score this from 0 to 3. It sends back a probability for every option of every question, from one pass through the model. There is no paragraph to read and nothing to parse. Your code reads the numbers and acts.
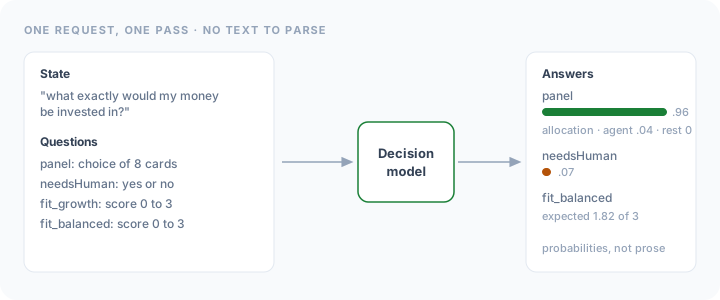
TypeSafe puts the difference from an LLM this way: an LLM “generates one token at a time, each conditioned on the last”, where Jev “generates all outputs in a single query”. Cloudflare’s model card says Clef “returns a probability for every allowed option of every question in a single forward pass.”
The job is old. Spam filters and intent routers have sorted text into labels for decades. Two things are new. The questions arrive with each request, so you don’t train a classifier per label set. And the models are built on LLMs: Clef is Qwen3.8-27B with a scoring head on top.
The reason they matter now is cost. When an agent handles a customer turn, its first model call often only works out what she is asking. In this study, Opus 5.5 working alone spent $0.021 a turn. One Jev call cost $0.000037. A decision model in front can make that first call unnecessary.
Who makes them
| Model | Maker | Weights | List price, input (October 2026) | In my test |
|---|---|---|---|---|
| Jev | TypeSafe | closed, API | $0.042 per million tokens, output free | full runs |
| Clef, Clef-flash | Cloudflare | open, Apache 2.0 | $0.24 and $0.09 per million on Workers AI | full runs |
| d1 | Liquid AI | closed, API | $0.04 per million on Vercel | decision only |
| Luna Decisions | OpenAI | closed, API (beta) | $0.10 per million, output free | decision only, added 8 Oct |
| Laya | Convai Innovations | open, Apache 2.0 | free | decision only |
| Kev | Jared Palmer | open | self-host | not tested |
The first five appeared between 15 September and 1 October 2026; OpenAI’s followed on 6 October. Before them, teams did this job with fine-tuned classifiers or a small LLM as a router, so I raced a Claude Haiku 4.5 router as well.
What I tested
One turn in a wealth-onboarding chat. A customer types a message, and the turn has to show the right one of eight prepared cards and write a sentence or two with facts from tools. I wrote 32 messages and ran each one through six AI models, from Amazon Nova Micro to Claude Fable 5.1, five ways: the model alone, and with Jev, Clef, Clef-flash or a Haiku router deciding the card first. Each setup is a BPMN process in Camunda, so swapping the decision maker meant swapping one box. 3,264 scored runs over one weekend.
The headline
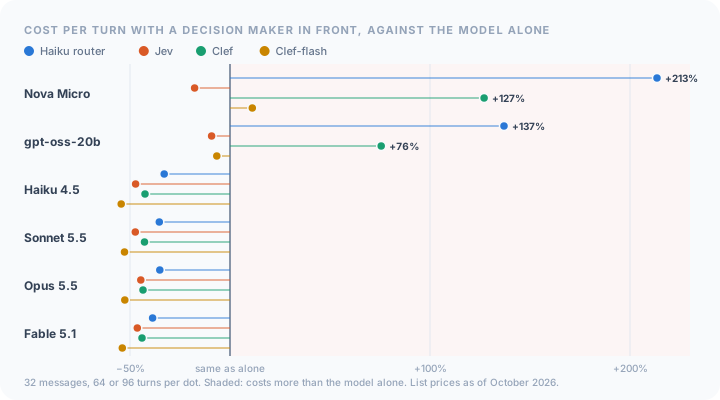
- On frontier models, every decision maker cut the cost of a turn by 35 to 54%.
- On the cheapest model, only Jev still saved money. One Clef call costs $0.00023, more than Nova Micro’s whole turn of $0.00013.
- Clef picked the right card on all 96 test calls when I sent it messages on its own, but it reports confidence on a different scale from Jev’s, so a rule tuned on Jev asked the customer more often.
Jev against Luna
OpenAI’s Decisions API runs on gpt-6-luna and went to public beta on 6 October 2026. I sent it the same requests as Jev, byte for byte, through Vercel’s AI Gateway: the 32 wealth messages above, and 40 items from a bank’s lending intake queue (uploads, broker emails, chats and system events, each routed to one of seven teams), three times each.
| Jev | Luna Decisions | |
|---|---|---|
| List price, per million input tokens | $0.042 | $0.10 |
| Right route, lending | 117 of 120 | 114 of 120 |
| Right card, wealth | 93 of 96 | 95 of 95 |
| Billed per call, both sets | $0.000030 | $0.000071 |
| Median time, lending | 244 ms | 214 ms |
Accuracy was close and changed with the job: Jev led on lending, Luna on the wealth messages. Cost was the difference. Luna billed about 2.3 times Jev per call across both sets, partly from its price and partly because the two count tokens differently for the same request. Luna was a little faster. I tested it on its own only, not inside the process, so the chart above does not include it.
The full guide
Read the full guide, free and open, with the interactive charts. It covers:
- Every model and setup side by side: right answers, cost and time per turn
- Each decision model on its own, before the full runs, now with Luna Decisions
- Jev against Luna on a lending queue, with the billed cost of every call
- Why Clef-flash asked the customer on 22% of turns, and what that says about thresholds
- Benchmark speed against speed inside a real process
- The one renamed field that would have silently switched off the handoff to a person
- A calculator for your own stack, and how I ran 3,264 turns
The one-paragraph version
A decision model returns probabilities for typed questions in one pass, which lets a rule decide before an agent spends a frontier-model call. On 32 messages and six models, every decision maker I tried cut the cost of a frontier turn by a third to a half; on the cheapest model only Jev, at $0.042 per million tokens, still saved money. What mattered most was the decision model’s price next to the turn behind it and the thresholds around it.
References
- TypeSafe, Introducing System One models and Jev
- Cloudflare, Clef decision models and the Clef model card
- Cloudflare, Workers AI pricing
- Liquid AI, Introducing d1
- OpenAI, Decisions API guide and API changelog
- Vercel, AI Gateway evaluation models
新的现场指南和剧集,直接发送到您的收件箱。无干扰,随时取消订阅。